On 7 January 2026 it snowed in Amsterdam in the morning and in Paris in the evening, and I was in both. In each city I recorded a few short reels to camera. Three days later, on a Paris street, I recorded one more. They were all about the same thing: what happens when the unexpected hits your infrastructure, and whether you are prepared for it.
This post collects what I said in those reels, cleaned up and joined into one argument. Then, because a reel is a minute long and a production system is not, it adds the checklist I would actually work through to prepare infrastructure for traffic spikes.
The morning of 7 January 2026: snow on the Amsterdam waterfront, a few minutes before I recorded the first reels.
There is no bad weather, only not being prepared
People say there is no such thing as bad weather, only not being prepared for it. I think the same is true in technology. Bad weather can hit your city, and it can also hit your IT infrastructure.
In infrastructure, the bad weather is demand. A lot of traffic, a lot of customers, all at once, like on Black Friday. If your infrastructure is not ready to handle that load, you are not prepared, and high demand can really collapse it.
The answer I gave in the reels was elasticity and scalability: infrastructure that can grow to match demand you can’t predict exactly. Kubernetes, Terraform and Ansible, used together, help you manage that condition. Observability and modern tooling help you see the demand coming and handle it. In the first take I also said AI can help forecast this kind of demand. I still think that’s right. A week later I saw a talk by ANWB, the Dutch motoring club, about how it forecasts roadside-assistance cases from inputs such as temperature and precipitation, using Prophet and XGBoost. A forecast is only useful if your platform can act on it, though, and that’s what most of this post is about.
Same morning, across the water: grey sky, snow on the roofs.
The herd always finds the database
The third take was about a specific scenario. Imagine an unexpected herd of new customers hitting your infrastructure. What happens? Your database collapses, and you can’t meet the demand.
I didn’t say why in the reel, so here is my take. The stateless tier is usually the easy part: Kubernetes adds pods, and a node autoscaler adds machines. The database is the shared, stateful thing every one of those new pods connects to. Scale the web tier tenfold without thinking about it and you have mostly built a faster way to overload the database. Elastic infrastructure means the whole path can absorb the herd, not just the part that is easy to scale.
Snow in Paris: the black swan for your infrastructure
That evening I was standing in front of Notre-Dame in the snow. Snow in Paris is exactly the kind of event nobody plans the day around. Some people call it a black swan. I asked the same question I’d asked in the morning: what if your black swan, your snow, happens to your IT infrastructure? Like snow in Paris, it can paralyse all the traffic, and with it your whole customer journey.
My answer: your system needs to be resilient, and the way you get there is by testing it. Use chaos engineering. Load-test your infrastructure. That way you are ready even for the edge cases, the circumstances you never tested in development. In the last take I put it as one line, and I’d keep it as the thesis of this post: architect your infrastructure in a resilient and predictable way, so it can survive unpredictable events. You can’t predict the snow. You can make your system’s behaviour in the snow predictable.
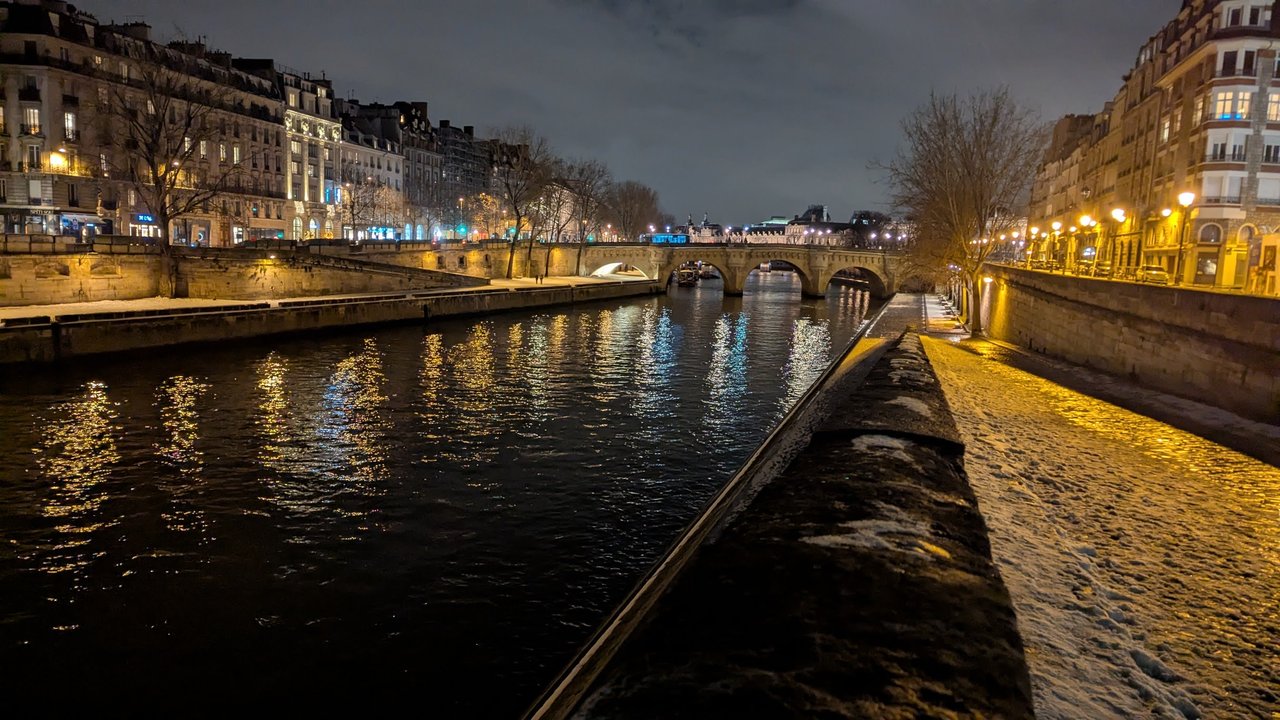
Left: Notre-Dame in the snow, where I recorded the evening reels. Right: a snowy quay along the Seine shortly after.
Millions rushing your small website
On 10 January I recorded one more reel on a Paris street. Beautiful architecture is timeless. If we want to build better architecture today, we need to build better apps, and better apps need better IT infrastructure. Infrastructure matters most on a very crowded day. In the digital world there could be millions of people rushing to your small, small website because everybody wants your product. I really hope you have that problem. With Kubernetes, Terraform and Ansible together, you can use the same technology big companies use.
That’s the point I want to stress: this isn’t only for hyperscalers. Every tool below is free to use, and a small team can run them.
A week earlier, on 3 January, I had recorded a reel in front of the ENIAC at an exhibit. I talked about how big it was, how far miniaturisation has come, and how useful it is to look at the past to spot the future. Hardware shrinks and gets replaced, but the questions about capacity, failure and demand stay the same.
A snow-day readiness checklist
Here is what “prepared” means in practice. Each item follows from something I said in the reels. Where I’ve already written a deep dive, I link to it rather than repeat it.
1. Capacity headroom and autoscaling
Elasticity is the first thing I mentioned, so start there, but know what each layer can and can’t do.
- Pods: Horizontal Pod Autoscaler. The HPA scales a Deployment or StatefulSet to match demand. Two details matter on a snow day. First, if containers don’t set the relevant resource request, CPU utilisation isn’t defined and the HPA takes no action for that metric. Second, look at the defaults: the controller syncs every 15 seconds, and default scale-up allows the larger of +100% or +4 pods per 15 seconds, while scale-down waits through a 300-second stabilisation window.
maxReplicashas no default, so you must choose it. Choose it from what the database can take, not from a round number. - Nodes: Cluster Autoscaler or Karpenter. The Kubernetes docs list both as the node autoscalers sponsored by SIG Autoscaling. They add nodes when pods can’t be scheduled. Note that consolidation decisions use pod resource requests, not real usage, which is one more reason to set honest requests. New nodes take time to arrive, so keep some headroom for the first minutes of a spike.
- Events: KEDA. KEDA works alongside the HPA and feeds it external metrics such as queue length from Kafka, RabbitMQ or SQS. It can also scale to and from zero. For demand you can forecast, like Black Friday or a product launch, the KEDA cron scaler scales a workload to
desiredReplicasbetween astartandendtime. That is where a forecast turns into capacity. I compared the two in KEDA vs HPA and covered setup in KEDA on Kubernetes.
2. Protect the database from the herd
- Connection pooling. Put PgBouncer (or your database’s equivalent) between the app and PostgreSQL. Its defaults are
max_client_conn100,default_pool_size20 per user/database pair andpool_mode = session. Pool mode, sizing from workers and the pitfalls are in my PgBouncer connection pooling for traffic spikes post. - Read replicas for read-heavy pages. PostgreSQL hot standby lets a replica serve read-only queries, but the docs say plainly that it is eventually consistent with the primary. Send catalogue and search reads there. Keep “did my order go through?” on the primary.
- Rate limiting and load shedding at the edge. Refuse excess requests cheaply before they reach the database. In NGINX,
limit_requses the leaky-bucket method with aburstallowance. Rejected requests get a 503 by default, andlimit_req_statuschanges that, for example to 429. - Queues for writes that can wait. Confirmation emails, analytics and stock syncs don’t need to happen inside the request. Put them on a queue and let KEDA scale the consumers on queue length, so the database sees a steady stream instead of the herd.
3. Load-test the spike, not the average day
I said in the reels to load-test so you’re ready for the edge cases. Grafana k6 has a dedicated spike test type for “sudden and massive rushes” such as ticket sales, launches and seasonal sales. Two details make the test honest:
- Use an open model. With the default closed model, a slower system automatically lowers the arrival rate, which k6 calls coordinated omission. The
ramping-arrival-rateexecutor keeps the herd coming regardless of response times. - Add thresholds. If any threshold fails, k6 exits with a non-zero code, so the test can gate a pipeline.
import http from 'k6/http';

export const options = {
  scenarios: {
    snow_day: {
      executor: 'ramping-arrival-rate',
      startRate: 50,          // requests per second on a normal day
      timeUnit: '1s',
      preAllocatedVUs: 200,
      maxVUs: 2000,
      stages: [
        { target: 50, duration: '5m' },    // normal day
        { target: 1000, duration: '1m' },  // the herd arrives
        { target: 1000, duration: '10m' }, // and stays
        { target: 50, duration: '2m' },
      ],
    },
  },
  thresholds: {
    http_req_failed: ['rate<0.01'],
    http_req_duration: ['p(95)<500'],
  },
};

export default function () {
  http.get(__ENV.TARGET_URL);
}
The numbers are placeholders. Take the baseline from your real traffic and the peak from your forecast, then multiply it, because the black swan won’t stop at your forecast. Watch the database while the test runs, not just the load generator.
4. Chaos experiments and a game day
Chaos engineering was the other half of my Paris answer. The Principles of Chaos Engineering define it as experimenting on a system “to build confidence in the system’s capability to withstand turbulent conditions in production”. You define a measurable steady state, hypothesise that it holds, inject real-world failures, and try to disprove the hypothesis while keeping the blast radius small.
On Kubernetes, two CNCF incubating projects do the injecting. Chaos Mesh has fault types such as PodChaos (pod-kill, pod-failure, container-kill) and Schedule and Workflow controllers to orchestrate them. LitmusChaos offers experiments from ChaosHub plus probes that check behaviour during a fault. There’s a Chaos Mesh example and the patterns to test (circuit breakers, bulkheads, retry budgets) in Infrastructure Resiliency: Patterns That Keep.
Then run a game day. The AWS Well-Architected Framework recommends conducting game days regularly with the same teams who would handle the real event, and warns against documenting procedures you never exercise. My minimal plan:
- Pick the scenario: “10x traffic in one minute while one database replica is down.”
- Write the hypothesis in SLO terms: “p95 stays under 500 ms and errors under 1%.”
- Agree the abort switch and who presses it.
- Run it: the k6 spike plus a Chaos Mesh or Litmus fault. Include a node drain, which is where a PodDisruptionBudget proves itself or doesn’t.
- Watch the dashboards and alerts you’d rely on during the real event.
- Write down what broke, what alerted late and which runbook step was wrong, then fix it and schedule the next one.
5. Observability, SLOs and alerting
Observability was in my very first take, because you can’t manage demand you can’t see. Instrument the request path with OpenTelemetry so a slow checkout traces down to the query behind it (OpenTelemetry on Kubernetes). Don’t forget the control plane: when everything scales at once, etcd metrics and alerts tell you if the cluster itself is struggling.
Alert on SLOs, not on CPU. Google’s SRE workbook recommends multiwindow, multi-burn-rate alerts. For a 30-day SLO, for example, it suggests paging when 2% of the error budget is consumed in one hour, a burn rate of 14.4, confirmed over a short five-minute window so the alert also resets quickly.
6. Infrastructure as code for a fast rebuild
Terraform and Ansible were in almost every reel, and this is why. Terraform is “an infrastructure as code tool that lets you build, change, and version cloud and on-prem resources safely and efficiently”. Ansible configures what runs on those resources. On a snow day, that means extra capacity, a new node pool or a whole replacement environment is a reviewed change, not someone clicking through a console under pressure. I wrote up how I split the two in Terraform vs Ansible: when to use which. Rehearse the rebuild during a game day: code you’ve never applied in anger is a hypothesis, not a plan.
7. Graceful degradation
Finally, decide in advance what you’ll switch off. Google’s SRE book chapter on handling overload suggests serving “degraded responses”, ones that are less accurate or contain less data but are easier to compute, and sums it up as “redirect when possible, serve degraded results when necessary”. In practice: put recommendations, live stock counters and heavy search filters behind feature flags. Cache the product page more aggressively. Show a polite queue page instead of a timeout. A customer who sees a simpler page still has a customer journey. A customer who sees a 504 doesn’t.
My take
Snow in Paris is rare. Traffic spikes aren’t: launches, campaigns, a mention in the press, or a product people really want. You can’t choose when your snow day comes. You can choose whether your platform is elastic, whether you’ve load-tested the herd, whether you’ve broken things on purpose before they broke on their own, and whether you can see and rebuild what’s happening. That’s what being prepared means.
If you want help getting there, I work on exactly this: finding the bottleneck before the herd does through performance optimisation, and designing elastic, rebuildable platforms on AWS, Azure and GCP through cloud infrastructure consulting.