Blog
1642+ articles — Page 20 of 69
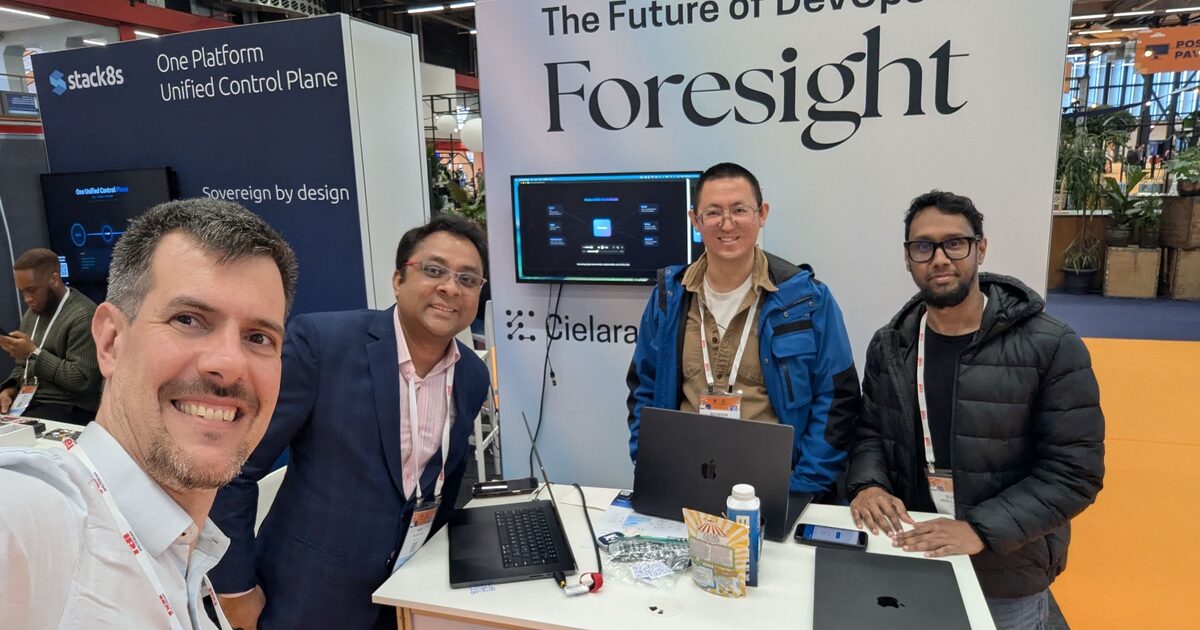
Cielara AI at KubeCon EU 2026: AI Writes Faster Than Review
Max Murshed of Cielara AI at KubeCon EU 2026: Foresight models your software architecture to catch review issues before they slow teams down.
3 min read
Jim Zemlin at KubeCon EU 2026: AI Makes Open Source Critical
Conversation with Jim Zemlin, Executive Director of The Linux Foundation, at KubeCon EU 2026. 2026 could be the year generative AI reshapes software.
3 min read
Coffee with Cloud Native Content Creators
Post-KubeCon coffee in Amsterdam with Chad McRowell, James Spurin, and Farshad Poye. Brainstorming content creation, technical storytelling, and building.
2 min read
KubeCon EU 2026: Dutch Kubernetes Podcast and Community
Connected with the team behind De Nederlandse Kubernetes Podcast and Nate Waddington from CNCF at KubeCon EU 2026 Amsterdam. The ecosystem is built.
2 min read
NetBird at KubeCon EU 2026: Open-Source
After-hours conversation at A'DAM Tower with Albert from DUO about NetBird — an open-source, European-built network overlay based on WireGuard that.
2 min read
OpenClaw Hackathon at AI House Amsterdam
Recap of the OpenClaw Hackathon at AI House Amsterdam. Company pitches from Picnic, Kilo Code, Azin, Orq.ai, and Google. Full-day hacking, demo prep.
4 min read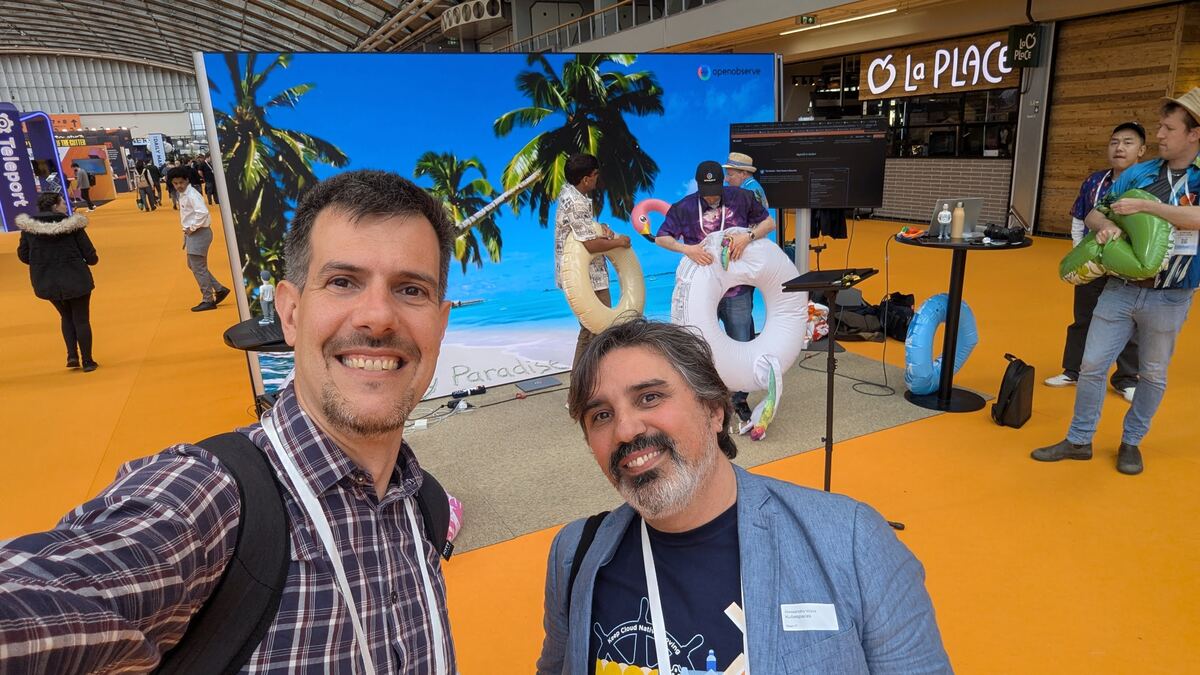
OpenObserve at KubeCon EU 2026: Rethinking
Met the OpenObserve team at KubeCon EU 2026 Amsterdam. Open-source unified observability platform handling petabytes per day with natural language queries.
2 min read
Paulo Menon at KubeCon EU 2026: GenAI and Kubernetes
Reconnected with former colleague Paulo Menon at KubeCon EU 2026 Amsterdam. Discussed the convergence of AI, MLOps, GitOps, and DevOps — plus his.
2 min read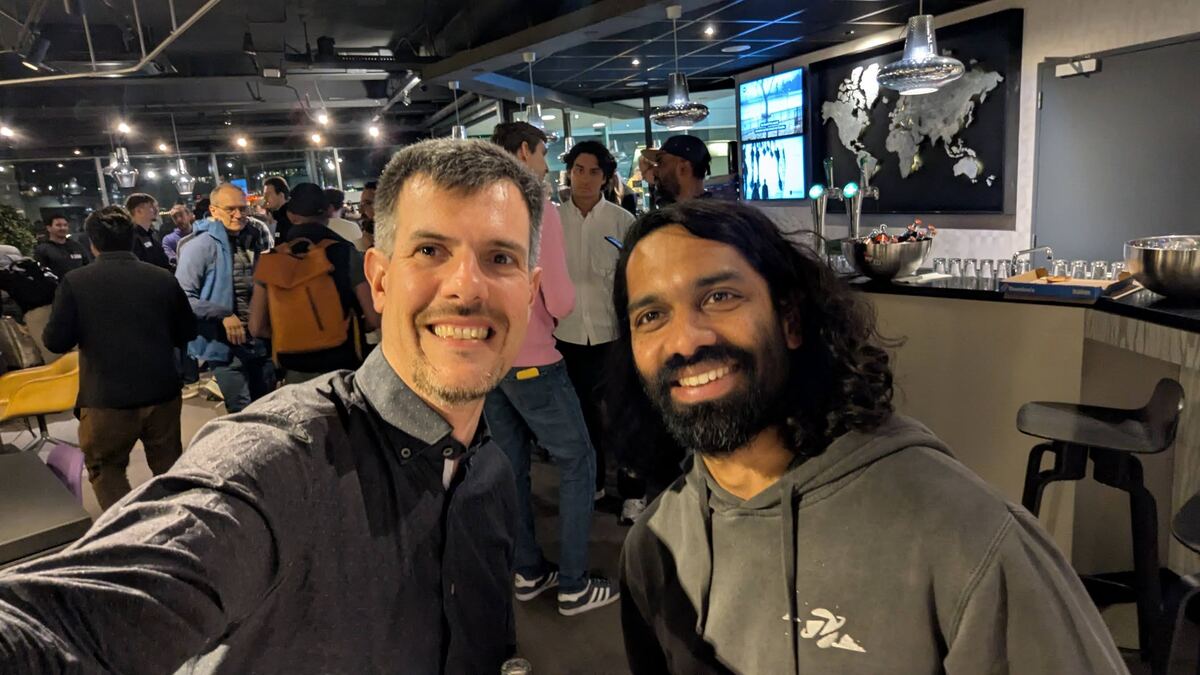
Building Autonomous Systems: KubeCon Meetup
Recap of the Building Autonomous Systems meetup during KubeCon EU 2026 week. LangChain sandboxed agents, Qodo hidden failure modes, SurrealDB knowledge.
4 min read
Stack8s at KubeCon EU 2026: Control Plane Across 15 Clouds
Visited the Stack8s booth at KubeCon EU 2026 and spoke with Valeria. Their approach: no infrastructure to manage — a unified control plane spanning 15+.
2 min read
NVIDIA Dynamo: Why It Replaces Triton for LLM Serving
NVIDIA Dynamo is the open-source successor to Triton. Disaggregated prefill/decode, KV-cache-aware routing, and 2-3x throughput gains for vLLM deployments.
7 min read
Deploy Custom Models on NIM Without NGC (Free Guide)
Deploy your own fine-tuned or custom model with NVIDIA NIM. Supports HuggingFace, NGC, S3, local paths, and air-gapped environments with step-by-step vLLM.
7 min read
NIM Model Profiles Explained: Pick the Right GPU Config
NIM model profiles control precision, parallelism, and backend for your LLM. Covers profile naming conventions, GPU memory tiers, selection chain priority.
6 min read
NVIDIA NIM Multi-Node on Kubernetes: 400B+ Model Deployment
Deploy 400B+ parameter models across multiple GPU nodes with NIM's Helm chart. Ray cluster formation, LeaderWorkerSet, shared storage, profile selection.
7 min read
NVIDIA NIM Support Matrix: Every Model × GPU × Profile
Complete 2026 NIM LLM support matrix: which models run on which GPUs, precision profiles (BF16, FP8, NVFP4, MXFP4), TP configs, and LoRA adapter support.
7 min read
Run:ai + Dynamo: Gang Scheduling for
NVIDIA Run:ai v2.23 with Dynamo enables gang scheduling and topology-aware placement for disaggregated prefill/decode inference workloads on GPU clusters.
4 min read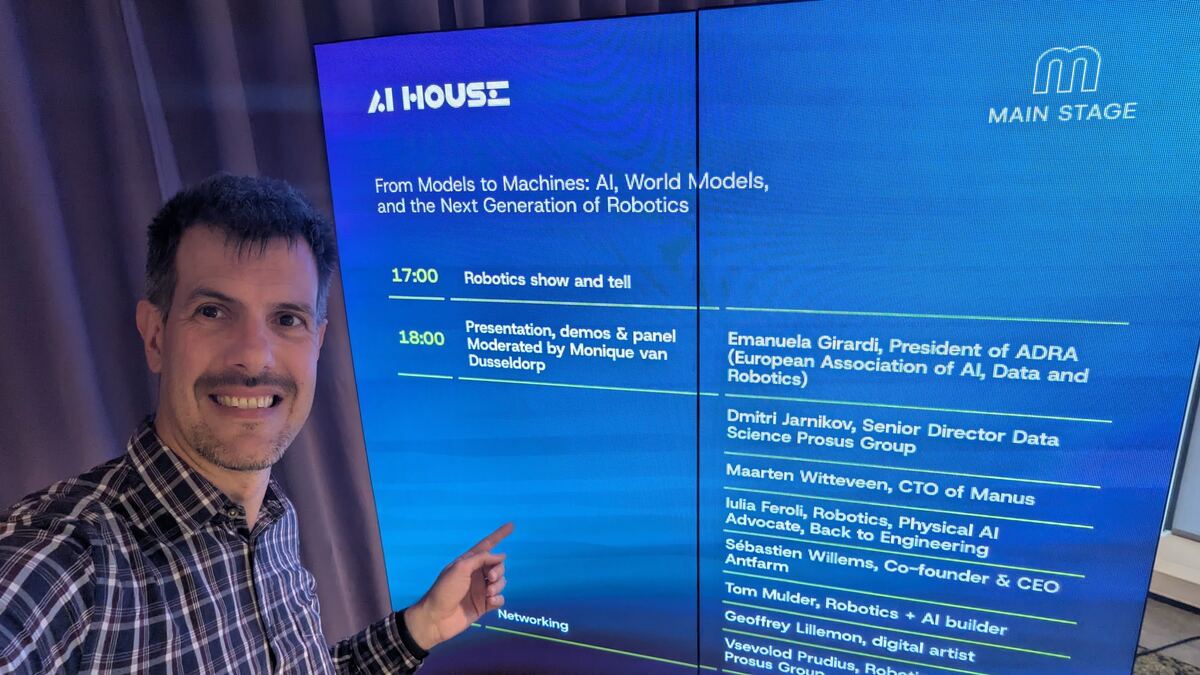
AI House Amsterdam: Models, Machines, and Robotics
Recap of the Models to Machines robotics event at AI House Amsterdam. 331 attendees, ADRA president on EU robotics strategy, Manus data gloves, General.
6 min read
GitOps Maturity Model: Manual to Full Automation (2026)
Assess your GitOps maturity across 5 levels — from manual kubectl to fully automated, policy-driven, multi-cluster GitOps with ArgoCD, Flux, and Crossplane.
3 min read
Kubernetes Security Hardening Checklist for
Production Kubernetes security in 50 checks. Pod security standards, RBAC, network policies, secrets management, image signing, runtime detection, and CIS.
3 min read
Enterprise LLM Deployment: On-Premises
Regulated industries cannot send data to OpenAI. On-premises LLM deployment patterns with vLLM, NVIDIA NIM, air-gapped clusters, and compliance architectures.
4 min read
Kubernetes Multi-Cluster Management:
Most enterprises run 5-50 Kubernetes clusters. Fleet management with Rancher, ArgoCD ApplicationSets, Cluster API, federation patterns, and GitOps at scale.
3 min read
NVIDIA NIM Multinode: Serving 400B+ Models Across GPUs
When a model is too large for one server, you need multinode inference. NVIDIA NIM multinode deployment with DeepSeek-R1, Llama 405B, tensor parallelism.
8 min read
Run:ai Distributed Inference: Large Model Serving Guide
NVIDIA Run:ai orchestrates distributed inference across GPU nodes with topology-aware scheduling, dynamic autoscaling, NIM support, and Dynamo pipelines.
8 min read
Deploy DeepSeek-R1 671B Distributed with Run:ai + NIM
Step-by-step tutorial deploying DeepSeek-R1 671B across 2 nodes with NVIDIA Run:ai. Covers Leader-Worker Sets, NIM profiles, SGLang runtime, and PVC caching.
9 min read